The demo works. The integration doesn't.
AI capability has become genuinely accessible. The models exist, the APIs are available, and the entry cost is low. The problem is that "accessible" and "production-ready" are different things. A demo that works against clean, controlled data often fails in production against real data: data that's messy, incomplete, inconsistently formatted, or arriving at volumes and speeds the demo never had to handle.
The integration layer is where most AI projects break down. The model is a component. Getting data into it reliably, getting outputs out of it in a usable format, handling failures gracefully, and connecting the whole thing to your existing systems. That's the engineering work. Most AI demos skip it entirely.
The question isn't whether AI can solve your problem. It's whether your data pipeline is reliable enough to feed it, and whether your team can act on the outputs it produces.
Where AI actually adds value, and where it doesn't
AI adds the most value in three types of problems: pattern recognition at scale (finding signals in data volumes humans can't process manually), natural language understanding (extracting structured information from unstructured text, classifying content, generating consistent responses), and prediction from historical data (forecasting, anomaly detection, recommendation).
It adds the least value (and the most risk) when it's applied to problems that are actually workflow problems. If the real issue is that your team has a manual process that's slow, the solution is usually better tooling or automation, not a model. AI on top of a broken process makes the process faster in the wrong direction.
The honest assessment before any AI project: is this a data problem (AI might help), or is it a process problem (fix the process first)? The answer changes the entire approach.
What production AI implementation actually involves
A production AI system has five layers that need to work together:
- Data ingestion: reliable pipelines that clean, normalise, and deliver data to the model in the format it expects. This is often 60% of the engineering work.
- Model layer: the actual AI component: a fine-tuned model, a third-party API, or a combination. The model choice depends on your accuracy requirements, latency constraints, and data privacy needs.
- Output handling: parsing model outputs, validating them, and routing them to the right downstream system. Models produce probabilistic outputs; your system needs to handle confidence thresholds and failure cases.
- Integration layer: connecting the AI system to your existing stack: databases, APIs, user interfaces, notification systems. This is where most production failures originate.
- Monitoring and feedback: tracking model performance over time, detecting drift, and capturing the feedback signals needed to improve accuracy. A model that's accurate today may degrade as the underlying data distribution shifts.
None of these layers are optional in a production system. Skipping any of them creates a system that works in demos but fails under real conditions.
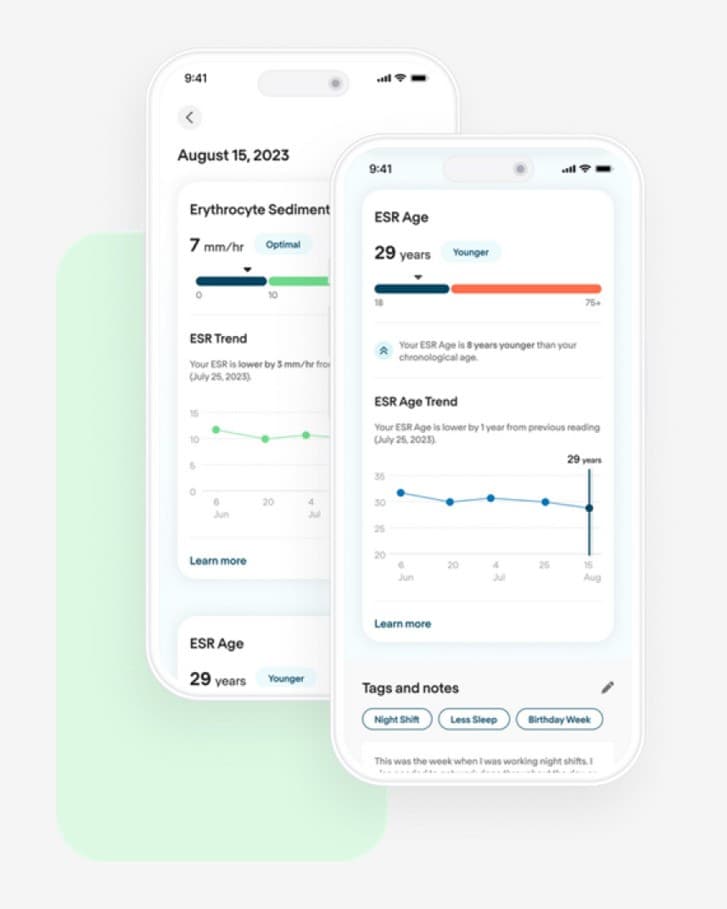 From our workThe AI reading model we built for COR Health reads ESR results with 99% accuracy, confirmed by COR.Read the case study
Build vs buy vs integrate: choosing the right approach
Most AI requirements don't need a custom-trained model. The foundation models available through APIs (OpenAI, Anthropic, Google, and others) are capable enough for most language and reasoning tasks. The engineering challenge is integrating them well, not training something from scratch.
Custom model training makes sense when: your problem requires domain-specific accuracy that general models can't achieve, your data can't leave your infrastructure for privacy or regulatory reasons, or you have enough labelled training data to make fine-tuning worthwhile.
For most business AI problems, the right approach is: use existing foundation models via API for general capability, apply prompt engineering and retrieval-augmented generation (RAG) to make them domain-aware, and invest engineering effort in the data pipeline and integration layer rather than the model itself.
What this looks like in practice: the COR Health AI layer
The COR Health platform reads an inflammation marker (ESR) from the COR One device. At launch, results were read with conventional image processing. It worked, but not well enough: the device housing is slightly transparent, so background noise leaked into the images, polluted the readings and meant a lot of manual checking.
The fix was not a cleverer filter. Once the platform had collected months of real device data, we trained a model on it. Readings now reach 99% accuracy, a figure COR has confirmed, and the manual effort is gone. The model only became possible because the data pipeline had been capturing clean, structured readings from day one.
That is the pattern in most production AI: the model is the last step. Reliable ingestion, enough real data, output validation and traceability come first, and that is where most of the engineering effort went.
We build practical AI systems for startups and product teams, focused on integration, reliability, and outcomes that actually work in production, not just in demos.